
Video prompt extraction
analyzes subjects, actions, environments, lighting, camera angles, and camera movement to create detailed prompts from reference footage.
TOOL-PROFIL TOOLAI
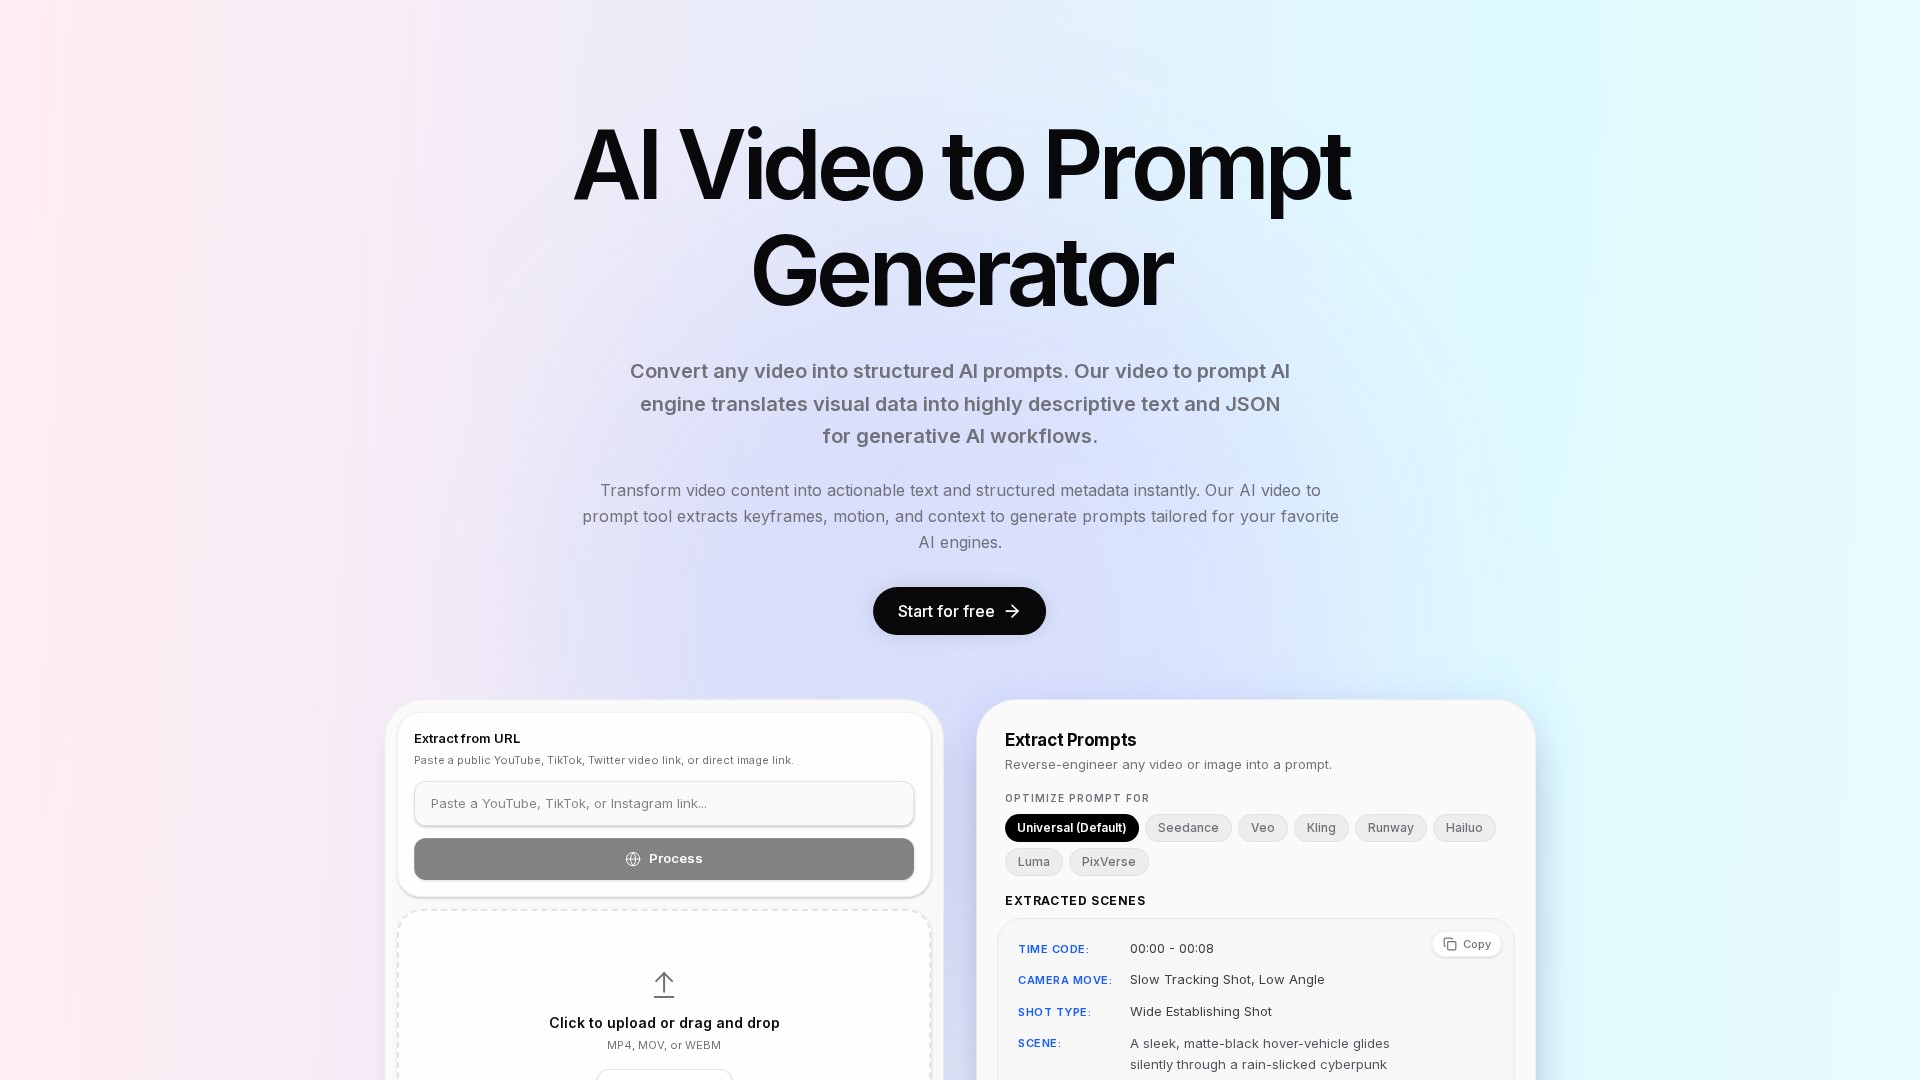
VideoInPrompt is an online tool that converts videos or images into descriptive AI prompts and structured JSON, analyzing subjects, motion, lighting, and cinematography with model-specific prompt optimization and API workflow integration.
 Gesamtes Bild anzeigen
DAS GROSSE BILD
VideoInPrompt centers on Video to Prompt AI, translating video visuals into natural-language prompts, structured text, and JSON metadata for generative AI creation, content repurposing, and automation. The platform also offers image-to-prompt, image-to-video, text-to-video, and text-to-image tools.
EIN GENAUERER BLICK
Erkunden Sie Produktansichten und veröffentlichte Beispiele. Öffnen Sie ein beliebiges Bild für eine genauere Ansicht.
WAS SIE TUN KÖNNEN
Lernen Sie die Möglichkeiten kennen. Finden Sie Ihren eigenen Weg, sie zu nutzen.
analyzes subjects, actions, environments, lighting, camera angles, and camera movement to create detailed prompts from reference footage.
reverse-engineers prompts from existing images and accepts direct image links.
includes time codes, camera moves, shot types, and scene descriptions. The demonstration shows a 00:00–00:08 segment with a slow, low-angle tracking shot and a wide establishing shot.
supports natural language, structured text, JSON schemas, and timestamped JSON timelines for programmatic processing.
offers Universal, Seedance, Veo, Kling, Runway, Hailuo, Luma, and PixVerse options.
supports public YouTube, TikTok, Twitter, and Vimeo video links, plus S3 links and local uploads.
accepts MP4, MOV, and WEBM through file selection or drag and drop.
a REST API enables SaaS integration, automated tagging, categorization, and downstream generative AI tasks. The FAQ specifically assigns full REST API access to the Enterprise tier.
FÜR IHREN WORKFLOW GEMACHT
analyze YouTube, TikTok, and Instagram videos to support new scripts, social posts, and summaries.
extract visual elements and pacing from competitor creatives to guide new generated assets.
turn product demonstrations into SEO-oriented product descriptions and structured metadata.
describe futuristic skylines, neon lighting, aerial motion, volumetric lighting, and atmosphere.
capture vertical handheld footage, natural daylight, fast jump cuts, and shallow depth of field.
identify macro close-ups, push-ins, lifestyle scenes, and premium lighting in wireless-earbud showcases.
extract exterior drone shots, stabilized interior tracking shots, slow pans, and natur
AUS DER COMMUNITY
Melden Sie sich an, um Ihre Erfahrungen zu teilen und anderen zu helfen, das richtige Tool zu finden.
IHRE NÄCHSTE ENTDECKUNG

Iterate.World ist eine Website, auf der Nutzer aller Erfahrungsstufen gemeinsam mit KI-Bildgeneratoren experimentieren können. Arbeite an Bildern zusammen, lerne von guten Prompts und probiere mehrere KI-Engines aus (DALL-E 2, Stable Diffusion, Openjourney). Gewinne kostenlose Credits im täglichen Spiel.
Mit ShortcutsGPT können Sie eigene Verknüpfungen für wiederkehrende Prompts erstellen und sparen sich, ChatGPT immer wieder dasselbe zu sagen.

GhibliAI verwandelt Texte und Bilder mithilfe fortschrittlicher KI-Technologie in Kunstwerke, die vom Stil des Studio Ghibli inspiriert sind.

Excompt ist ein Website-Cloner und Komponenten-Extraktor, der jede Website in sauberen, produktionsfertigen HTML-, React- oder Vue-Code mit Tailwind-CSS-Styling umwandelt.
MACHEN SIE DEN NÄCHSTEN SCHRITT
Besuchen Sie die offizielle Website, um die neuesten Funktionen zu entdecken und loszulegen.